CallLens
Sales calls transcribed, scored by an LLM, searchable by meaning
Every sales call transcribed, scored, and searchable. CallLens ingests a call via signed webhook, transcribes it with diarization, scores each rep against a configurable scorecard with a structured-output LLM, builds embeddings for semantic search, and serves the whole thing through a Cube-powered analytics cabinet. Zero GPUs. Single Hetzner box.
- Sector
- AI · SaaS
- Stack
- Symfony 7.4 · PostgreSQL 17 · Next.js 15 · Cube
- GPUs Required
- 0
- Vector Dimensions
- 1024
- Pipeline Stages
- 5
- Monthly Infra Cost
- ≈€60
Sales Coaching That Actually Reads the Calls
Most sales teams record their calls. Almost none get them scored consistently — managers don't have the hours, and scorecards don't enforce themselves. CallLens automates the read: every call ingested, every rep scored, every objection searchable.
We built it on the cheap-by-design principle: all heavy AI runs through external HTTP APIs (Deepgram for STT, OpenAI for scoring + embeddings), no GPU needed, a single Hetzner dedicated server is sufficient. Provider-independent interfaces let you swap or self-host later without touching business logic.
Score sales calls reliably with an LLM that never hallucinates an evidence quote, persist 1024-dim utterance embeddings for semantic search at scale, give managers a Cube-powered analytics cabinet — and do it all on a single Hetzner server with one Docker stack and no GPU.
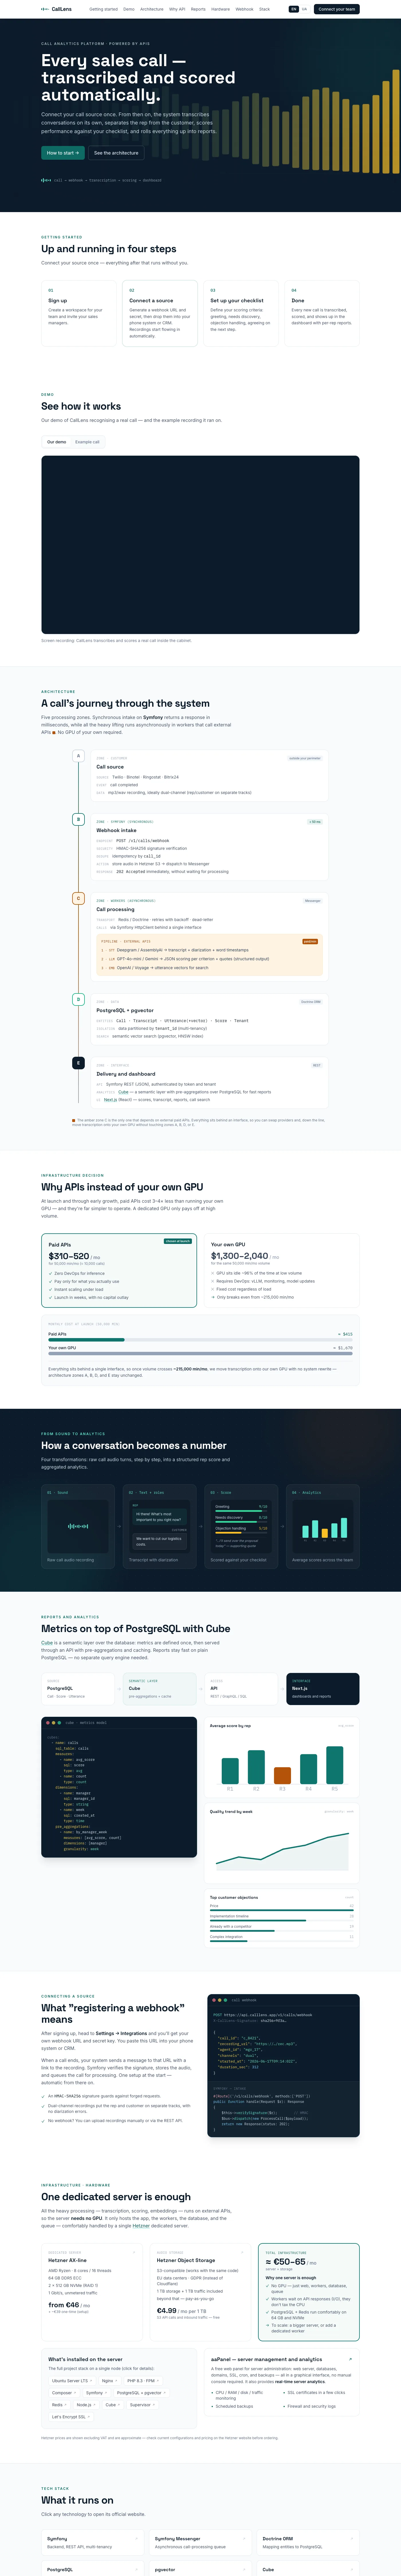
Symfony 7.4 + PHP 8.5 backed by PostgreSQL 17 + pgvector (HNSW), API Platform generating OpenAPI 3.1, a Messenger pipeline that walks each call through transcribe → score → embed states (idempotent, retryable), Cube as the semantic analytics layer, and a Next.js 15 cabinet on top. The scorer enforces structured JSON output and validates every evidence quote against the actual transcript.
Built for the Sales Manager
- 01
Webhook + Manual Ingest
HMAC-signed webhooks from any telephony/CRM (Twilio, Binotel, Ringostat, Bitrix24) plus manual upload via REST. Idempotent by tenant + external call ID.
- 02
Diarized Transcription
Deepgram for STT with per-channel labelling for dual-channel audio and provider diarization for mono. Word timings persisted on every utterance.
- 03
LLM Scoring with Evidence
Per-criterion scoring with strict JSON schema, an evidence quote per score, and the quote validated to appear in the transcript. No vibes scoring.
- 04
Semantic Search
1024-dim pgvector embeddings on every utterance, HNSW index, tenant-scoped ANN. Ask 'where did the rep handle objections' and get the actual moments.
- 05
Cube Analytics
Pre-aggregated dashboards on Postgres — avg score per agent, trend over time, top objections, score distribution. No second search engine for reports.
- 06
Configurable Audio Retention
keep, delete-after-processing, or delete-after-N-days, per tenant. Scheduler sweeps run nightly; transcripts and scores remain even after audio is deleted.
See It in Action

Under the Hood
Single Docker stack, single Hetzner box, single Postgres. All heavy AI work goes through external APIs behind narrow interfaces — swap providers in a config line, or move to self-hosted GPU later when the cost curve crosses over (~215k audio-minutes/month).
- Symfony 7.4
- PHP 8.5 API + Workflow
- PostgreSQL 17
- + pgvector (HNSW)
- Next.js 15
- Landing + docs + cabinet
- Cube
- Analytics over Postgres
Need AI-Native Tooling for Your Team?
From sales coaching to support analytics, we ship AI products that get the heavy lifting right — strict structured outputs, evidence-grounded answers, and stacks you can actually operate.
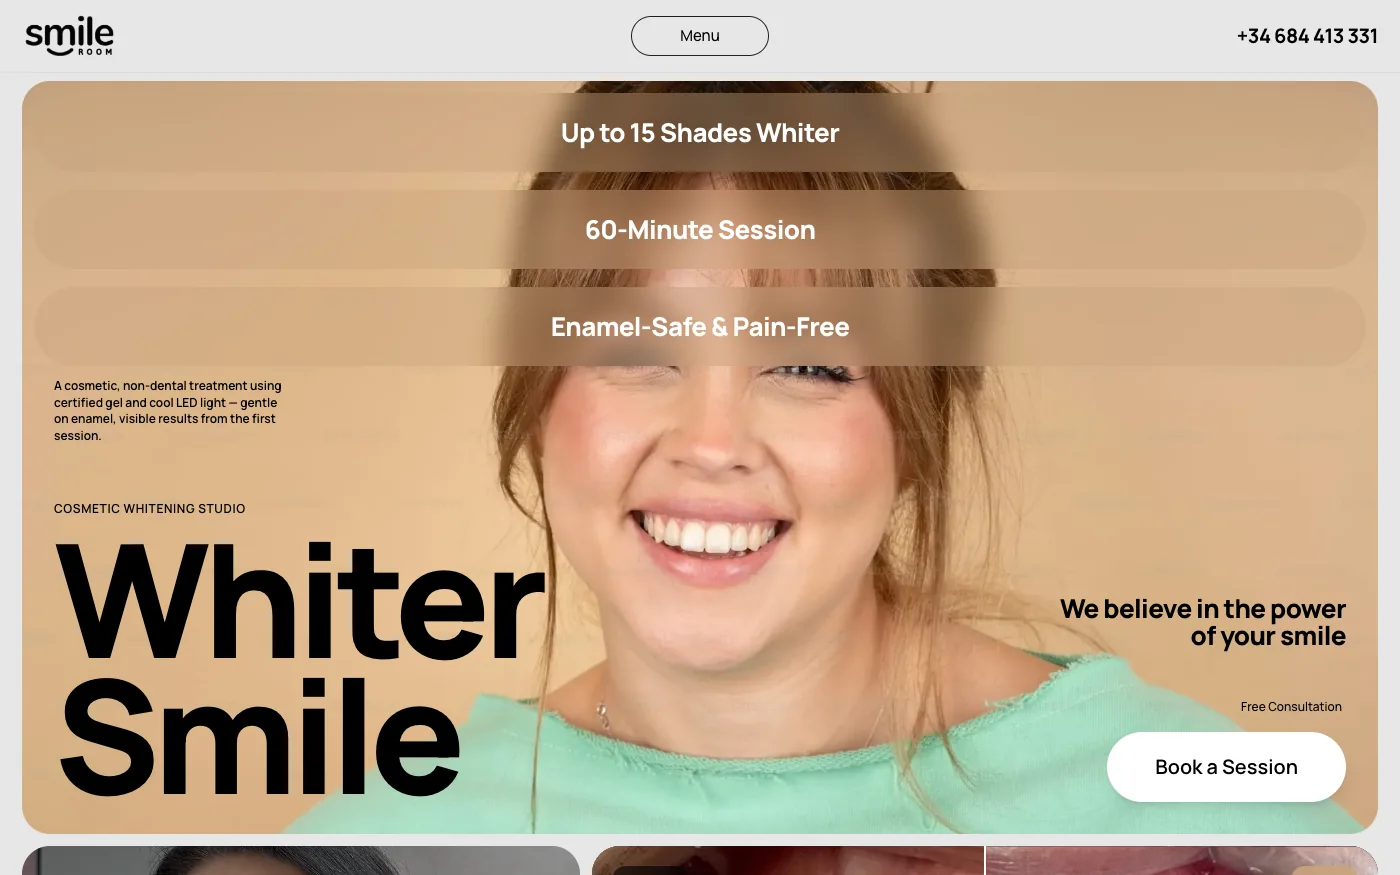
Sonrisa Blanca
Booking-led website for a teeth-whitening studio
Let’s talk.
Tell us what you’re building. You’ll get a reply and a first estimate within 24 hours.
Fill in the brief →